d-Matrix Adopts NVIDIA NVLink Fusion for Rack-Scale XPU Deployment
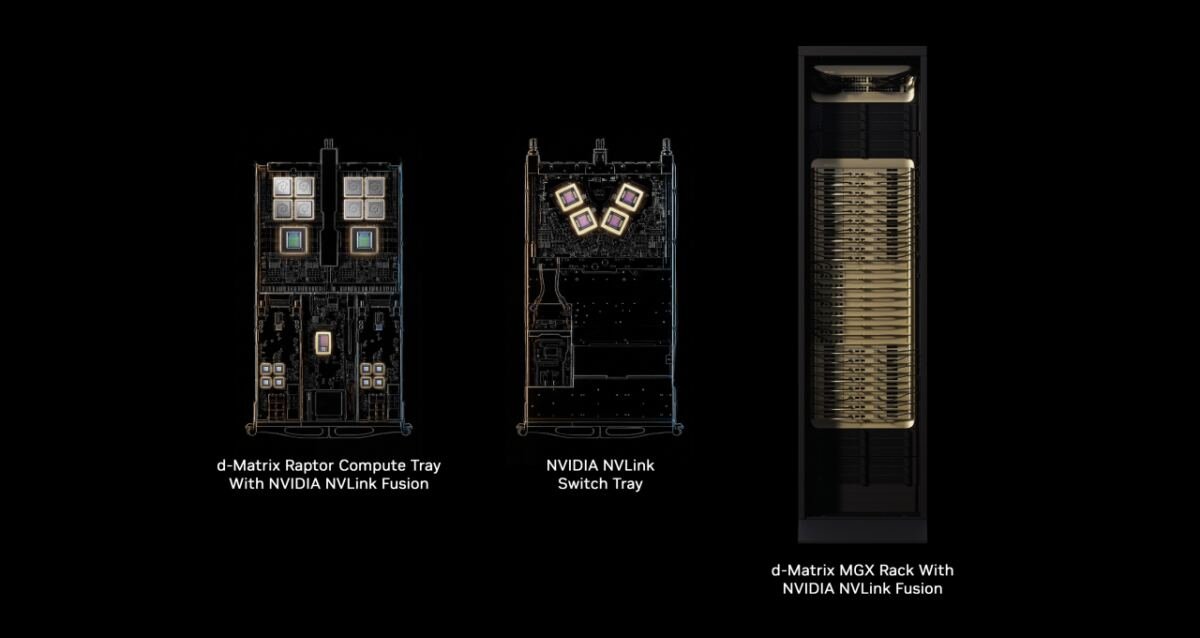
AI inference chipmaker d-Matrix today announced it will use NVIDIA NVLink Fusion to connect its next-generation Raptor XPUs to NVIDIA’s AI infrastructure platform — joining a growing roster of ecosystem partners. By connecting Raptor to NVIDIA NVLink scale-up and Spectrum-X scale-out networking, the NVIDIA MGX rack architecture and the broader NVIDIA AI platform, NVLink Fusion gives d-Matrix an accelerated, lower-risk path from custom silicon to large-scale deployment. “Demand for inference is soaring, but capital, time and energy remain finite,” said Sid Sheth, cofounder and CEO of d-Matrix during a press briefing yesterday.
“With NVLink Fusion and MGX, we can integrate our Raptor XPUs into a broadly deployed, liquid-cooled architecture, giving customers a faster, lower-risk path to deploy and scale ultralow-latency inference.” The NVIDIA AI platform is vertically integrated and horizontally open. NVLink Fusion extends this openness to XPUs and CPUs, allowing silicon companies to focus on their processor innovations while using NVIDIA infrastructure to deploy them at AI factory scale. From Custom Silicon to Rack-Scale Deployment NVLink Fusion — Quick Reference What is NVIDIA NVLink Fusion? NVIDIA’s platform for integrating third-party custom XPUs and CPUs with NVLink scale-up networking, MGX rack architecture, and the full AI factory platform — spanning compute, networking, storage, security, power, cooling and software. What problem does it solve? Building a custom XPU is hard. Deploying one at scale is harder. NVLink Fusion lets XPU makers skip building rack-scale infrastructure from scratch and plug directly into NVIDIA’s proven, globally deployed AI factory platform. How fast is it? 3x lower XPU-to-XPU latency than off-the-shelf Ethernet, 10x higher packet rates, and 3 TB/s per XPU of all-to-all bandwidth via sixth-generation NVLink. Who are the partners? d-Matrix, AWS, Arm, Intel, Fujitsu, SiFive, Alchip, Astera Labs, GUC, Marvell, MediaTek, Samsung, Cadence, Synopsys, Ayar Labs and Lightmatter. What CPU architectures does it support? All major CPU architectures — Arm, x86 and RISC-V — alongside NVIDIA GPUs. What is a semi-custom AI factory?



