LFM2.5-VL-3B for Better and Faster Vision Capabilities for the Edge
Hugging Face how we trained our most capable vision-language model Benchmark results Inference speed on CPU and GPU How to use LFM2.5-VL-3B LFM2.5-VL-3B demo Get Started Citation LFM2.5-VL-3B is our most capable vision-language model you can run on your own hardware. It understands documents and screens alike, grounds objects, and can call tools.
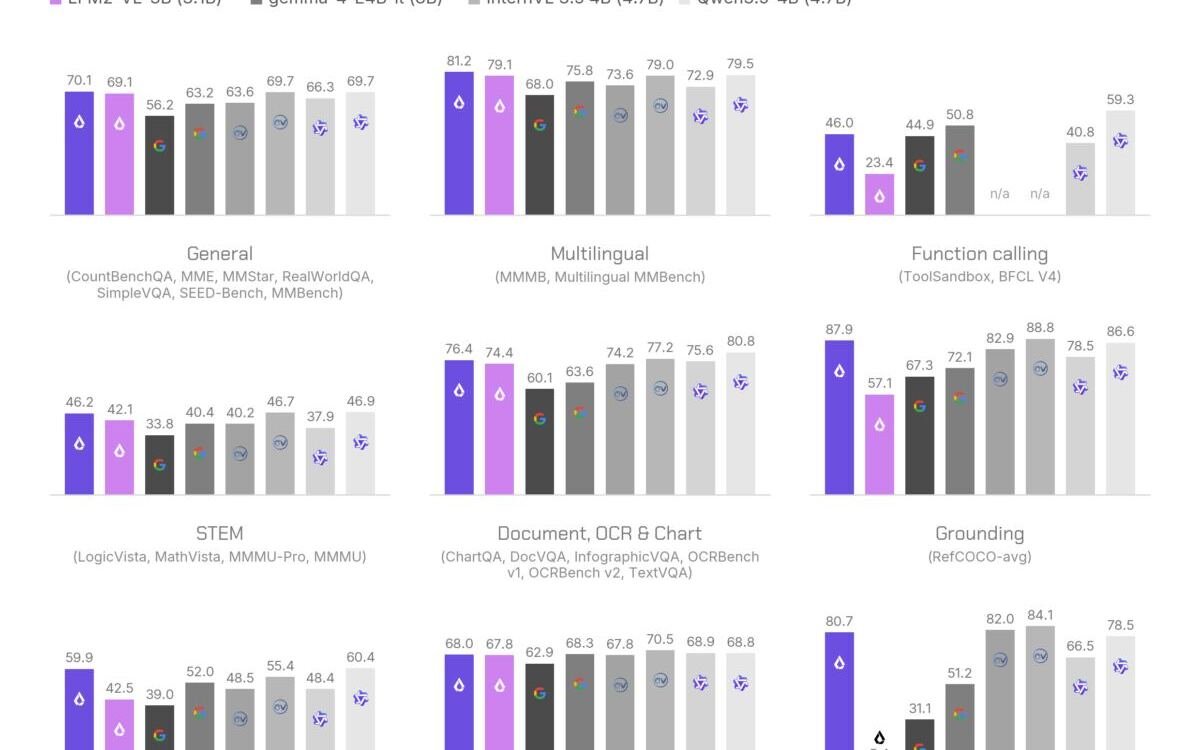
It answers directly instead of reasoning, so responses stay fast in real-time and on-device apps. LFM2.5-VL-3B extends the vision-language capabilities of our previous releases with four major improvements: How we trained our most capable vision-language model LFM2.5-VL-3B pairs a SigLIP2 400M NaFlex vision encoder with the same pre-trained backbone as our LFM2.5-2.6B text model. It is pre-trained on about 34T tokens, with 4x more vision data than before, drawn from curated and synthetic image-caption, OCR, grounding, and instruction-following sets. To support non-Latin scripts, we doubled the vocabulary to 128K by extending the tokenizer in place rather than retraining from scratch. Post-training runs in two stages: First is supervised fine-tuning (SFT), with knowledge distillation from a larger teacher and Antidoom training. Second is multi-reward reinforcement learning (RL). We evaluated LFM2.5-VL-3B across both vision and text benchmarks. The vision benchmarks cover multilingual visual comprehension, instruction following, visual math and scientific reasoning, document understanding, object detection, multi-image understanding, and screen understanding. LFM2.5-VL-3B leads its size class on real-world image tasks, while also reading digital content well, from documents and charts to on-screen UI elements. *All values in the table are normalized to 0–100. Evaluation is done using vLLM 0.26.0 and each model’s recommended generation parameters when available. Non-reasoning mode is used everywhere, and models are prompted to directly answer without reasoning. We also evaluated LFM2.5-VL-3B on text-only benchmarks for instruction following and tool use. Instruction following climbs across the board, and tool use improves sharply. On tool use, LFM2.5-VL-3B is on par with Gemma-4-E2B and Qwen3.5-2B.