Nvidia says its Groq 3 LPX is four times faster than Cerebras, but the math is more complicated
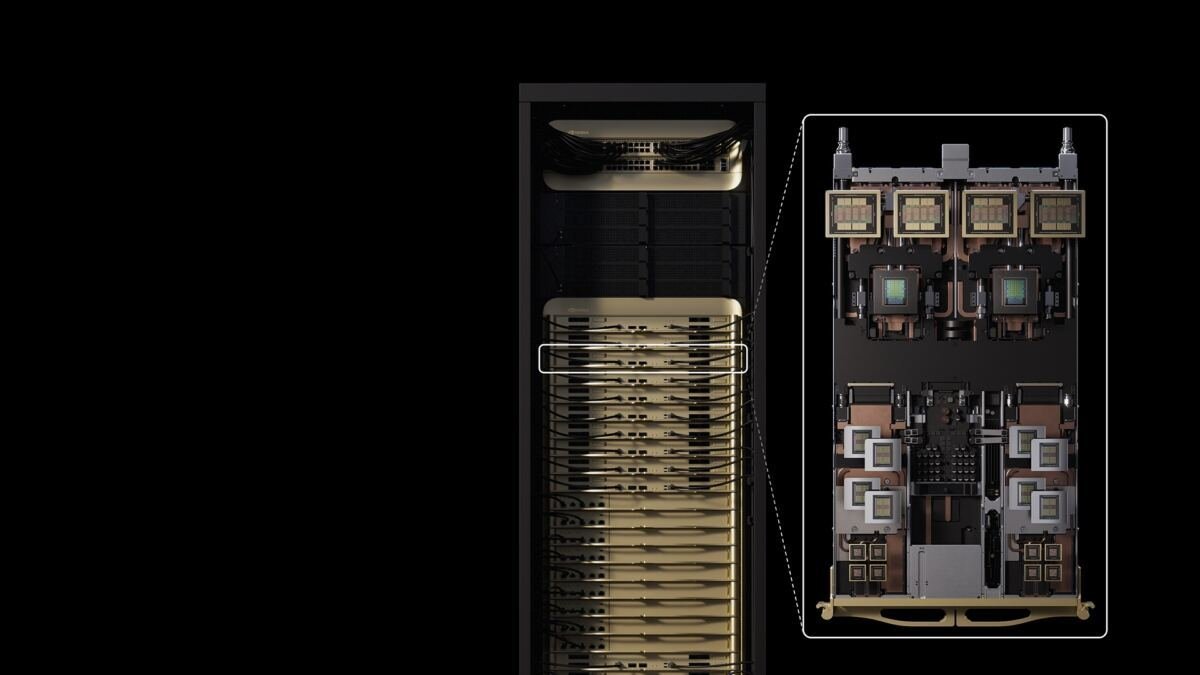
Nvidia has moved its specialized inference accelerator, the Groq 3 LPX, into full production. An independent benchmark shows top numbers for token generation, but experts warn the comparison is stacked in Nvidia’s favor.
At the Hot Chips 2026 conference, Nvidia announced that its Groq 3 LPX has entered full production. The chip, which Nvidia calls an “interactive AI inference accelerator,” extends the Vera Rubin platform and is built to deliver ultrafast token generation for agentic AI systems. Nvidia says it will go live later this year. In late December, the company paid about $20 billion for the Groq license and brought on founder Jonathan Ross and president Sunny Madra. Groq builds processors tuned for inference rather than AI training.Ad Speed is important for agentic applications, as agents burn through huge amounts of tokens across hundreds to thousands of inference steps. The faster a system generates tokens, the more reasoning steps and tool calls fit into the same window of time. So within a wait time users find acceptable, an agent can iterate more often, check files, write and test code, and verify results. Nvidia says this cuts coding tasks down to “minutes instead of hours.”Ad A benchmark from Artificial Analysis is meant to show how fast the Groq 3 LPX runs: On the open model Gemma 4 31B with a 100,000-token context window, the LPX rack hit 3,400 tokens per second, measured across 50 back-to-back requests. Performance held steady between 10,000 and 100,000 tokens of input length. It’s the highest figure ever recorded for this model. Nvidia says that makes the accelerator four times faster than the next best option, the Cerebras chip, at 882 tokens per second. Groq relies on an SRAM-heavy dataflow architecture. The catch, according to The Register, is that each LPU has just 500 MB of memory, 576 times less than a Rubin GPU with 288 GB. So models get split across several accelerators over Ethernet, with a single rack holding up to 256 LPUs. In this mixed setup, GPUs handle the compute-heavy prefill phase and the LPUs handle the bandwidth-heavy decode phase.Ad In this setup, The Register points out, Gemma 4 31B is a best-case scenario: a dense model that fits entirely in one rack.



