Quantization-Aware Healing: a compressed, 4-bit model that outperforms its full-precision original
Hugging Face why the usual healing methods fall short here Our approach Results QAH against QAT, head to head What this changes in practice Making a large language model smaller almost always comes with a cost. The now-standard recipe for efficient deployment is to compress the architecture first, cutting the parameter count by removing layers, heads, or neurons, and then quantize the remaining weights down to 4 bits to shrink memory and compute further.
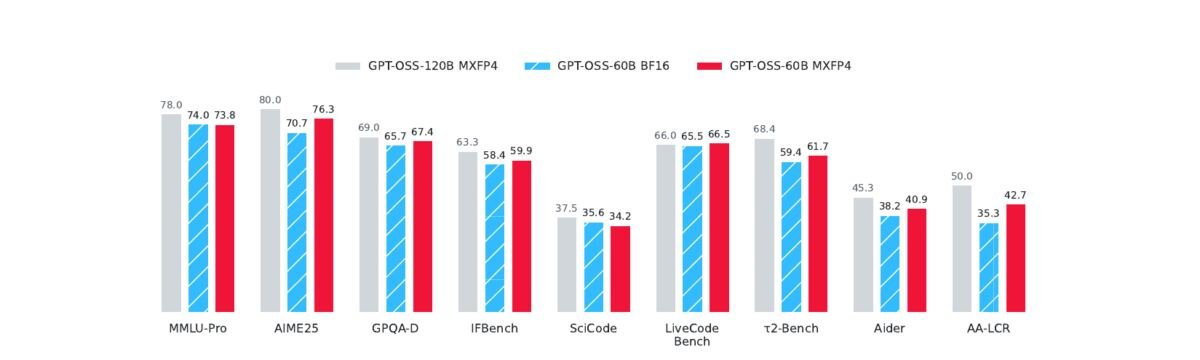
Both steps save a lot, but together they systematically degrade the capabilities people actually care about: reasoning, mathematical problem-solving, and code generation. Because of this, serious deployment pipelines add a recovery step, usually called healing, before the model goes into production. Recent open-weight releases such as gpt-oss, NVIDIA’s Nemotron family, and our own Hypernova 60B all rely on some version of this compress-then-heal approach. Our latest paper, Quantization-Aware Healing: A Practical Recipe for Recovering Compressed, 4-Bit LLMs, asks a question that the field has mostly left open: once a model has already been through structural compression, not just quantization, how well does that recovery step actually work, and what is the right way to do it? We introduce Quantization-Aware Healing (QAH), and applied to a GPT-OSS 120B model compressed to 60B parameters and quantized to MXFP4, it produces a model that beats its own full-precision (bfloat16) version on 7 of 9 benchmarks. The 4-bit model ends up smaller, cheaper to run, and more accurate than the checkpoint it was quantized from. This inverts the usual relationship between a 4-bit model and the 16-bit model it came from. Most efficiency pipelines follow the same three steps: compress the architecture, quantize the compressed weights, then heal the damage. The difference between methods is entirely in that last step. The dominant healing recipe is quantization-aware training (QAT). It inserts fake-quantization operators into the forward pass and keeps fine-tuning the model on a task loss, so the weights learn to tolerate the low-precision representation. In practice this means re-running an already expensive multi-stage post-training process, supervised fine-tuning, RLHF, agentic tuning, through a noisier, lower-precision forward pass. It is costly, and as our results show, it can also become unstable if training continues too long past its best point. An alternative, quantization-aware distillation (QAD), avoids re-running that history. Instead of a task loss, it distills a frozen full-precision teacher directly into the quantized student through a KL-divergence loss on the output logits.



